
You know the feeling at the end of a good session with a chatbot. The explanation landed, the pieces fit, and you close the laptop lighter than you opened it.
That feeling has stopped being evidence that you have learnt anything of value.
In this post I will:
Show what three studies published this summer found about perceived learning and measured learning.
Explain why reaching for the Dunning-Kruger effect gets this half right and half wrong.
Give paid subscribers a four-move protocol to combat this unlearning.
The study that measured the gap
In June, researchers at Sungkyunkwan University published a study in Interactive Learning Environments. Eighty-eight students worked through questions at high-school level. The researchers split learning into three stages, understanding the concept, solving the problem, and reviewing the answer, then randomly assigned students to use GPT-4o at one of them.
Students who used AI during problem solving scored higher on the later test than students who used it only for concept understanding.
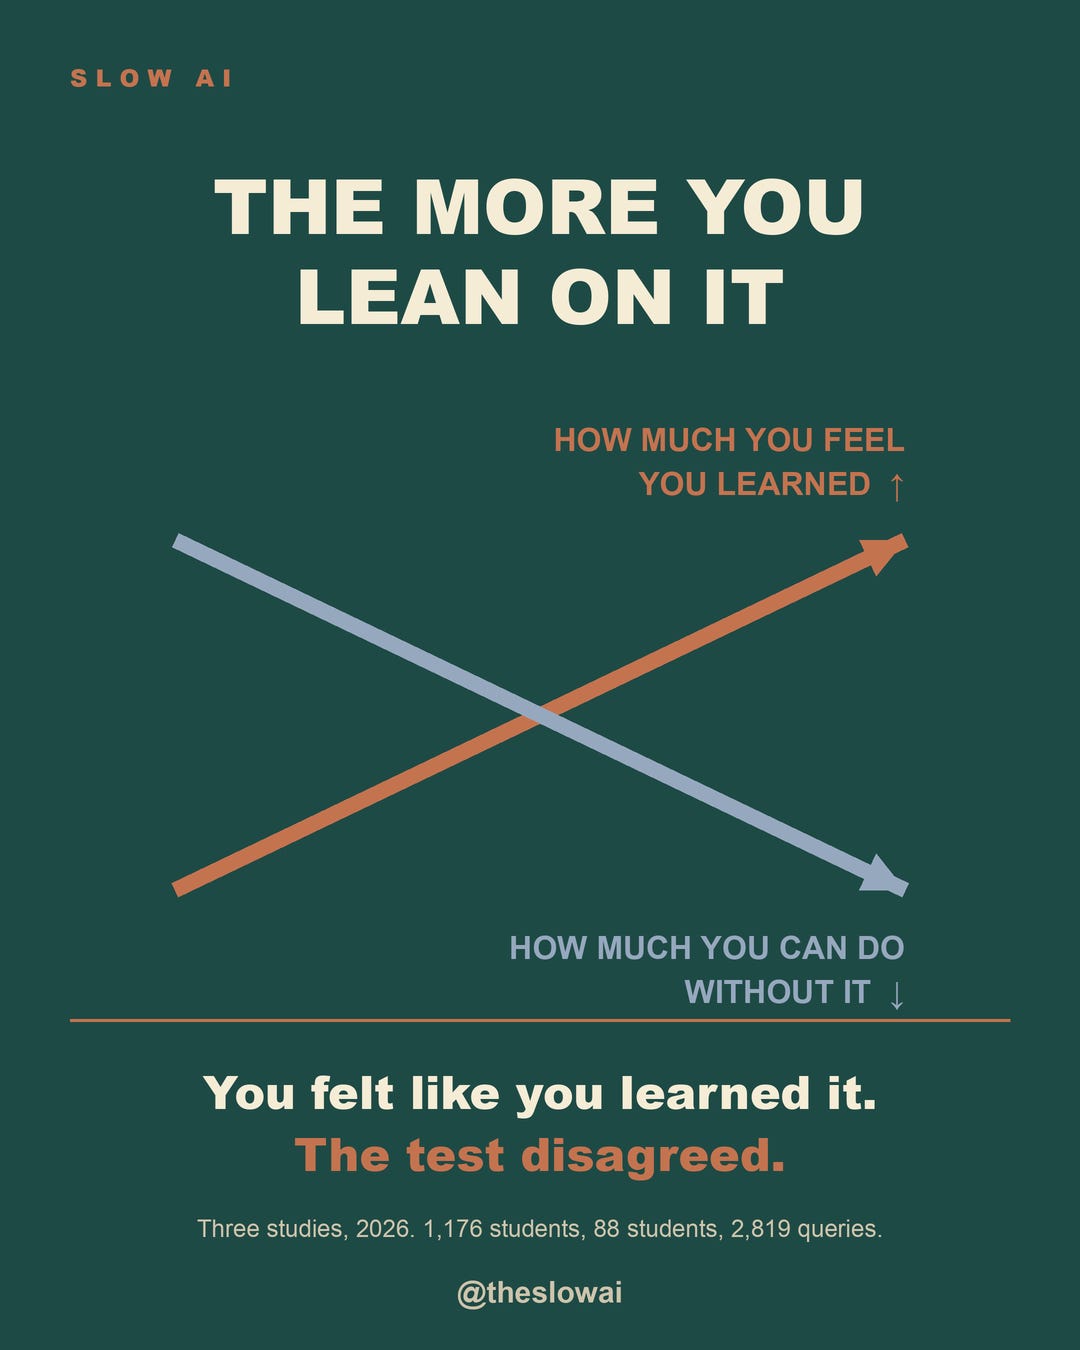
Inside that problem-solving group, the students who leaned on the tool hardest scored lower on the objective test while reporting higher perceived learning and higher satisfaction.
They felt they had understood. The test disagreed.
Eighty-eight students at one institution is a small base, but it adds to a growing base of literature. In the words of one of the researchers:
“Generative AI is a powerful tool that increases learning efficiency, but relying on it uncritically can lead to the paradoxical result of lowering objective academic achievement.”
Why everyone will call this Dunning-Kruger, and why that is only half right
Justin Kruger and David Dunning published Unskilled and Unaware of It in 1999. The skills needed to do something well are often the skills needed to judge whether you have done it well, so the least competent are the worst placed to notice.
The version that reached the internet is a graph showing a peak of unearned confidence in beginners. That graph has taken a beating. In 2020, Gilles Gignac and Marcin Zajenkowski published The Dunning-Kruger effect is (mostly) a statistical artefact in Intelligence, arguing the pattern is largely produced by the way the comparison is set up. Analyse self-estimates against scores the way the original work did, and much of the effect appears whether or not the phenomenon is there.
What the Sungkyunkwan University researchers measured is a different kind of phenomenon. Nobody was asked to guess their percentile against strangers. They compared how much students believed they had learned against how much they demonstrably had, in the same task, with the AI tool as the variable.
The (false) confidence is coming from the tool.
What the tool does to you
What follows is my reading rather than a finding in any of the studies I quote.
Understanding feels like fluency, like the click when an explanation lands. A good AI explanation produces that click reliably, because coherent and well-pitched is what it is optimised for. What it does not produce is the effortful retrieval, the wrong turns, and the reconstruction that generate the competence underneath.
You get the sensation of learning without the process that causes it.
A student can use AI exactly as permitted, do all the reading, feel the click, and walk out with less than the student who struggled.
The signal we trusted was the feeling. That feeling can now be manufactured to order.
My book Slow AI works through more arguments like this one in full.
The fix is cheap, and it has nothing to do with detectors
Another trial across four universities and 1,176 students tested this directly. One small change to the order of a task protected what students could still do once the tool was taken away.
Below the line: that trial, a third study on what separates the students who gain from the ones who decline, and the four-move protocol I use to combat this.
The trial that shows what to do
In July, Huseyin Ates published a multisite, cluster-randomised field experiment in the International Journal of Educational Technology in Higher Education. One thousand, one hundred and seventy-six first-year students, across four universities and a period of ten weeks.
There were four conditions that were tested: peer feedback only, AI feedback delivered straight away, AI feedback given only after the student had assessed their own draft against the criteria, and a hybrid adding peer comment and a memo explaining what they accepted and rejected.
On the draft in front of them, the AI helped everyone. Then students sat a supervised task with no AI and no internet. There, the conditions where students judged their own work first came out ahead of the condition where the AI spoke first.
An exploratory result: the penalty for going straight to the AI was worst among students with the lowest baseline feedback literacy. This means that the people least equipped to evaluate a critique were the most damaged by receiving one.
What you ask decides what you get
Published at the end of July in the same journal, Yuan-Hsuan Lee and Jiun-Yu Wu logged 2,819 chatbot queries from 97 students.
More than a quarter never used it at all.
Among those who did, the students who improved most started with weaker achievement and asked broad, conceptual questions. The students who declined asked narrow procedural ones, despite starting with stronger knowledge.
The protocol
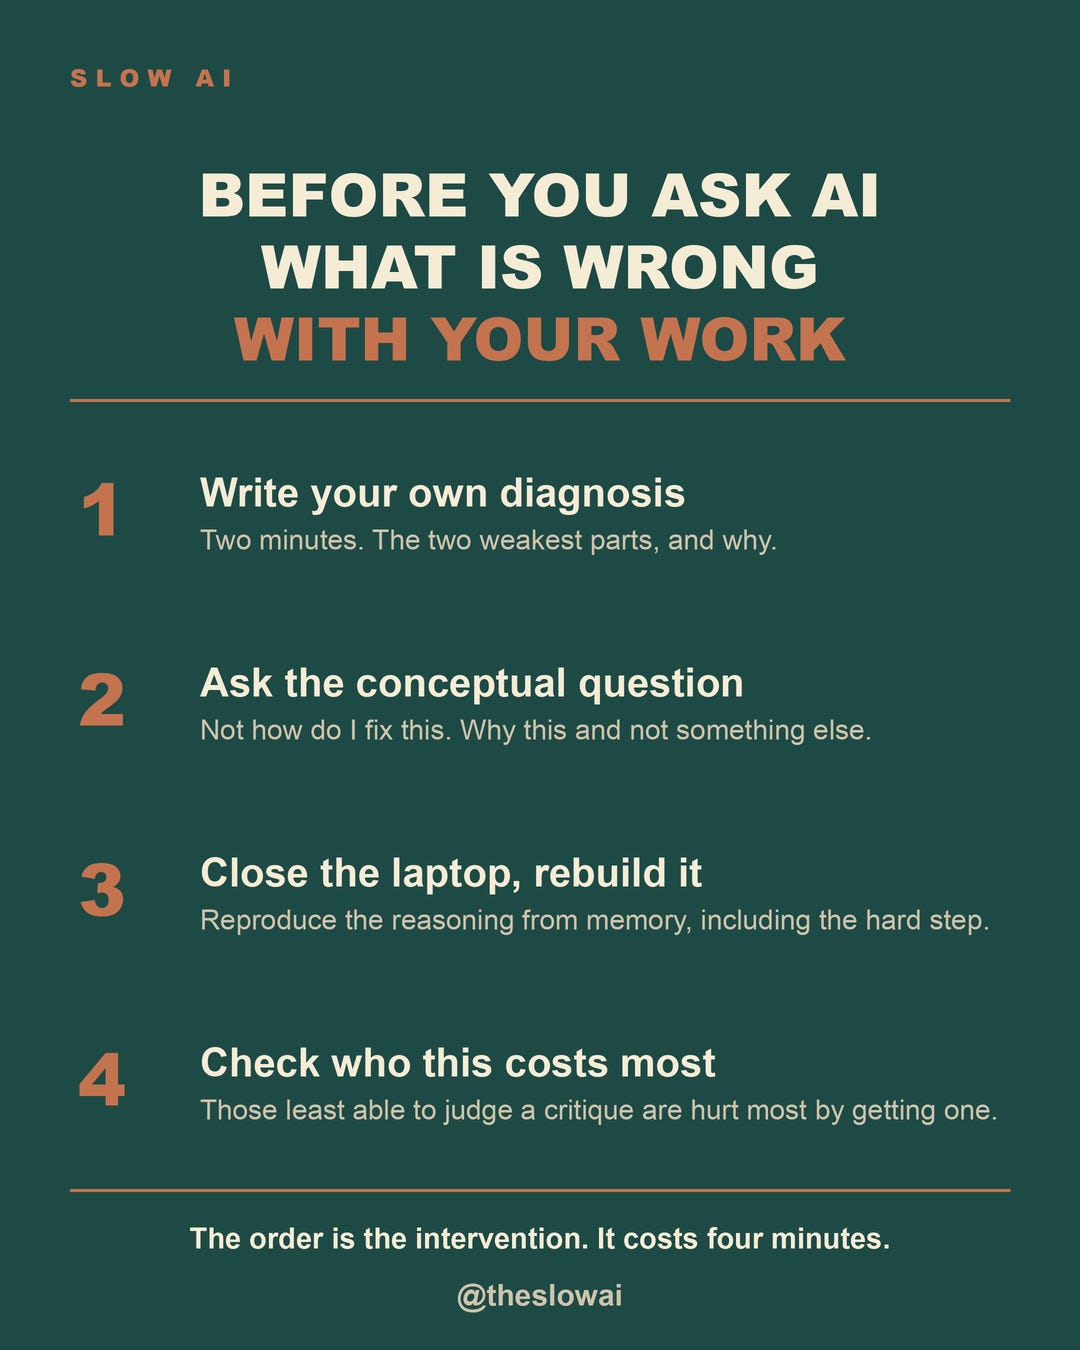
One: write your diagnosis before the model writes its own
Open a blank page before you open the tool, and write down the two weakest parts of your work, and why.
You are not producing a document. You are producing a comparison point, so that when the critique arrives you have something of your own to weigh it against.
Then paste this in:
Before you give me any feedback, ask me three questions about what I was trying to do. Then stop and wait. I will tell you what I think the two weakest parts are. Only after that, give me your critique, and tell me specifically where you disagree with my own diagnosis.
A model that has to disagree with you by name cannot simply agree with everything, which is its default failure.
Two: ask the broad question, not the narrow one
Procedural questions get you unstuck. Conceptual questions get you competent. Use this prompt:
I am about to ask you a how-to question. Before you answer it, tell me what conceptual question I should be asking instead, and why the version I was going to ask would leave a gap in my understanding.
Three: close the laptop and reproduce it
Shut the window. Write, from memory, the argument you have just been helped with. Not a summary. The reasoning, including the step you found hardest.
Reproduction from memory is a proxy rather than a definition, and it is a far better proxy than the feeling of having followed along.
Four: notice who this costs most
The students most harmed by unfiltered AI critique were those with the least feedback literacy to begin with.
If you teach, that changes where you spend your effort. The students who need the scaffold are the least likely to ask for it, because asking requires the judgement the scaffold is meant to build.
If you manage people, the same applies to your juniors, and nobody has given them a rubric.
What this is really about
Four years of arguing about whether students are cheating with AI, and the more uncomfortable finding is that a student can follow every rule and come out with less.
Read your own confidence as evidence that needs checking, the same way you would read a confident claim from anyone who stood to benefit from your believing it.
Go slow.